AI assistant SaaS

Ingest docs into a vector index, answer through an orchestrator, retriever and LLM gateway with citations, and trace every step for evals.
Offered as a template
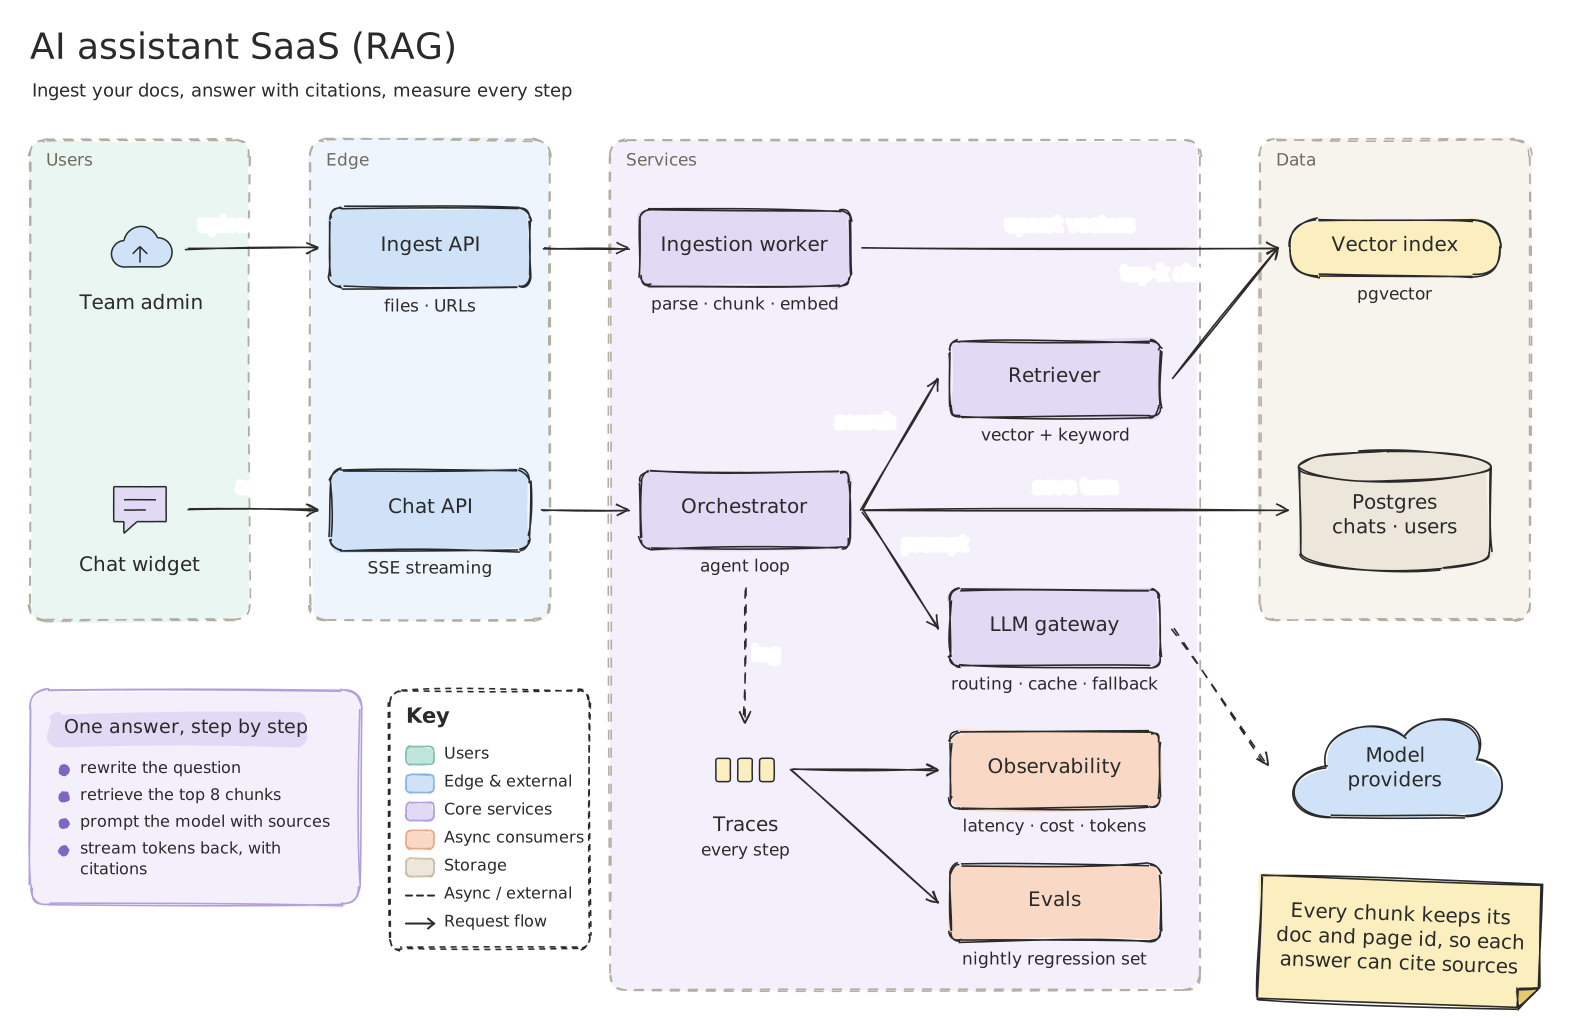
In this diagram
- AI assistant SaaS (RAG)
- Ingest your docs, answer with citations, measure every step
- Users
- Team admin
- Chat widget
- Edge
- Ingest API
- files · URLs
- Chat API
- SSE streaming
- Services
- Ingestion worker
- parse · chunk · embed
- Orchestrator
- agent loop
- Retriever
- vector + keyword
- LLM gateway
- routing · cache · fallback
- Traces
- every step
- Observability
- latency · cost · tokens
- Evals
- nightly regression set
- Data
- Vector index
- pgvector
- Postgres chats · users
- Model providers
- One answer, step by step
- rewrite the question
- retrieve the top 8 chunks
- prompt the model with sources
- stream tokens back, with citations
- Key
- mint Users
- sky Edge & external
- lilac Core services
- peach Async consumers
- sand Storage
- dashed Async / external
- arrow Request flow
- Every chunk keeps its doc and page id, so each answer can cite sources
- upload docs
- job
- upsert vectors
- ask
- save turn
- search
- top-k chunks
- prompt
- log
- API calls